AI
How RLHF Works: The Three-Stage Pipeline That Aligns Large Language Models With Human Intent
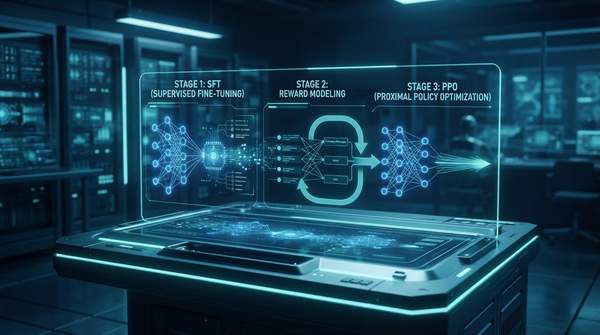
Reinforcement Learning from Human Feedback (RLHF) is a three-stage process that aligns large language models with human intent. It details supervised fine-tuning, reward model training with human preferences, and reinforcement learning optimization using PPO.
Arjun Mehta·November 15, 2026