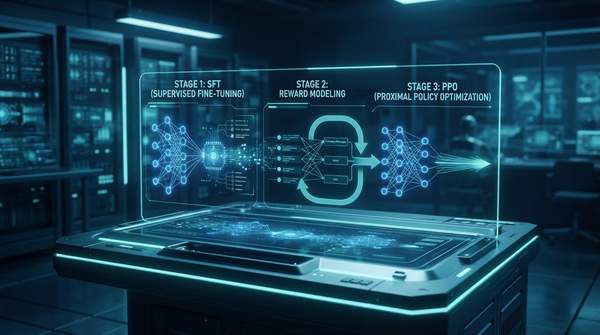
Reinforcement Learning from Human Feedback (RLHF) turns a raw, next-word-predicting language model into an assistant that follows instructions and reflects human preferences. It does so through three sequential stages: supervised fine-tuning on human-written demonstrations, training a reward model on human preference rankings, and finally optimizing the language model with a reinforcement learning algorithm, most commonly Proximal Policy Optimization (PPO). This article walks through each stage, showing which model is trained, on which data, and where the process can go wrong.
Introduction to RLHF: Aligning AI With Human Intent
RLHF is prominent in natural language understanding but is also used across other generative AI applications, as Amazon Web Services explains. Models can be trained on pre-generated human data, but adding human feedback loops significantly enhances model performance compared to its initial state—for instance, producing translations that sound natural rather than merely technically correct.
The deeper motivation, as IBM notes, is that some goals resist algorithmic definition: it would be impractical or even impossible to define "funny" in mathematical terms, but easy for humans to rate jokes generated by a large language model. That human feedback, distilled into a reward function, can then be used to improve the model's joke-writing ability. RLHF's roots trace to a 2017 paper by OpenAI's Paul F. Christiano and colleagues from OpenAI and DeepMind, which detailed success in training models for Atari games and simulated robotic locomotion.
AI companies and researchers often claim that RLHF fine-tuning ensures that the language models they market conform to human values—responding in ways that are "helpful," "harmless," and "honest," the so-called 3Hs, as a critique paper on arXiv observes. The sections below explain how the standard pipeline actually pursues that goal.
Stage 1: Supervised Fine-Tuning (SFT) for Instruction Following
The process begins with data collection: humans interact with the language model and provide demonstrations of ideal responses to various prompts, and this feedback is used to create a high-quality dataset of prompt-response pairs. The language model is then trained with supervised fine-tuning on this data, allowing it to learn and mimic human-like answers as a strong starting point, in the words of Weights & Biases's overview.
The purpose of this stage is format as much as content. As IBM explains, pre-training optimizes models for completion—predicting the next words in a sequence—by replicating linguistic patterns learned during pre-training. Sometimes a model will complete a sequence in a way a user doesn't want: given the prompt "teach me how to make a resumé," the model might respond "using Microsoft Word," a valid completion but one that misses the user's actual goal.
Hugging Face's technical blog by Nathan Lambert and colleagues frames the same point structurally: RLHF is challenging because it involves a multiple-model training process with different deployment stages, but the training breaks into three core steps—starting from a language model already pretrained with classical pretraining objectives. Supervised fine-tuning primes the model for instruction-following before any explicit reinforcement learning begins. This stage also matters for later training quality, because it's the SFT model that generates the candidate responses humans will rank in the next stage.
Stage 2: Training the Reward Model With Human Preferences
The reward model is a central component of RLHF, as Weights & Biases emphasizes. Instead of judging every model output by hand, developers train a separate model to predict which responses humans would prefer.
The data comes from comparison: human annotators rank multiple responses from the SFT model for a given prompt, and this preference data trains the reward model to assign a scalar score to any response. Chip Huyen's technical write-up illustrates the practical scale of this annotation problem with a real figure: one reference labeling effort showed inter-labeler agreement around 73%, meaning that if 10 people rank two responses, about 7 will agree on the ordering. To speed up labeling, each annotator ranks multiple responses at once—four ranked responses (A > B > C > D) yield six ranked pairs.
Two implications follow from these mechanics. First, the reward model can only be as reliable as the consistency of the humans whose preferences it distills; disagreement is not hypothetical but measurable. Second, the reward model is a proxy, not the humans themselves—its scores are what the final stage optimizes, which makes the quality of that proxy the central vulnerability of the whole pipeline.
Stage 3: Reinforcement Learning Optimization (PPO)
In the final phase, the SFT model is further trained so that its output responses maximize the scores from the reward model. Today, most practitioners use Proximal Policy Optimization, a reinforcement learning algorithm released by OpenAI in 2017, as Chip Huyen explains. The setup is unusual for RL: there is no game environment or physical task—instead, the policy being optimized is the language model, prompts are the states, generated responses are the actions, and the reward model's scalar score serves as the reward function.
The PPO algorithm updates the policy model toward responses that earn higher reward-model scores. A typical implementation loads a copy of the SFT model to serve as a reference behavior during training, so the optimization can be measured against the starting point rather than drifting unconstrained. Carnegie Mellon University's ML@CMU tutorial, by Zhaolin Gao of the Machine Learning Department, describes this iterative structure explicitly: a single training iteration can be repeated in a loop, initializing each iteration with the model trained in the previous one, and the same tutorial also notes that newer methods such as REBEL avoid PPO's complexity—clipping, critic models, and related machinery—in favor of stronger theoretical guarantees. PPO nonetheless remains the standard choice in the three-stage framing this article follows.
The Three Stages of RLHF: An Explanatory Model
The table below deconstructs the full RLHF training loop into its component stages, mapping what is trained, with what data, and toward what outcome:
| Stage | Model trained | Input data | Outcome |
|---|---|---|---|
| 1. Supervised fine-tuning (SFT) | Base pretrained language model | Prompt–response pairs written by human demonstrators | An SFT model primed to follow instructions and produce expected response formats before reinforcement learning |
| 2. Reward model training | Separate reward model | Human preference rankings of multiple SFT-model responses (with inter-labeler agreement around 73% in one cited labeling effort) | A model that assigns scalar reward scores approximating human preferences |
| 3. Reinforcement learning optimization | The SFT model as policy, updated with PPO (OpenAI, 2017), with a copy kept as reference | Prompts, sampled responses, and reward-model scores; iterations repeat with the previous iteration's model | A policy model whose responses maximize reward-model scores while staying measurable close to the reference |
Read as a sequence, the pipeline shows a progressive narrowing: a general-purpose pretrained model first acquires the form of helpful responses, then that form is scored against human taste, then the scores drive the policy update. Each stage's output is the next stage's essential input—SFT produces the candidate responses humans rank, the rankings produce the reward model, and the reward model steers the final policy.
The Critical Role of the KL Divergence Penalty
The final stage has a built-in failure mode: a policy that chases reward-model scores without constraint can drift into degenerate output, a phenomenon practitioners call reward hacking. The standard safeguard is a Kullback–Leibler (KL) divergence penalty included in the PPO objective, which penalizes the policy for deviating from the initial SFT model's distribution.
The underlying mathematics makes the logic precise. As the Wikipedia article on RLHF describes the derivation, one can solve directly for the optimal policy using Lagrange multipliers, giving a Boltzmann-style form: the optimal policy equals the SFT policy times an exponential of the reward, normalized by a partition function. That direct solution is unfortunately not tractable, since computing the normalization requires summing over all possible responses. Inverting the relationship expresses the reward implicitly in terms of the optimal policy, with the reward appearing as a β-scaled log ratio between the optimal policy and the SFT policy.
The practical consequence for implementers: the temperature parameter β controls how far the optimized policy may move from its SFT starting point. With the penalty in place, the policy is rewarded for alignment but penalized for straying from behaviors the SFT model already mastered—preserving core language capabilities and guarding against catastrophic forgetting while the model optimizes toward human-preferred responses.
Goals and Practical Challenges of RLHF
The stated goal is ambitious. RLHF presents itself as a method for AI oversight and AI safety through value alignment, and it is often claimed—by AI companies and researchers, as the arXiv critique puts it—that RLHF fine-tuning ensures models conform to human values, particularly the 3Hs: helpful, harmless, honest. In language-model practice, the intent is to produce more natural-sounding text and plausible conversational responses in chatbot-style settings.
But the same sources expose the gap between goal and guarantee. RLHF's effectiveness is highly dependent on the quality and consistency of the human feedback it distills, and annotation at scale is hard: a 73% inter-labeler agreement figure means roughly 3 in 10 pairwise rankings disagree, so the reward model inherits that noise. Inconsistent human labeling can lead to models that do not reliably reflect the desired values.
The challenges compound across stages rather than cancelling out: SFT quality shapes what annotators see, annotation noise shapes the reward model, and a flawed reward model steers the policy toward the wrong optimum—which is precisely where the KL penalty becomes the practical constraint that limits how much damage an imperfect reward signal can do.
Aligning AI With Human Intent: Key Takeaways for RLHF
Implementing RLHF effectively requires careful management of human annotation quality and strategic application of regularization techniques like the KL penalty to ensure model alignment without degradation. Practically, that means treating the three stages as interdependent: demonstrations chosen for SFT determine what annotators later evaluate, annotation protocols determine the reward model's reliability, and the KL penalty's strength determines how far the policy can chase that reward before losing the language capabilities it started with.
Two boundaries apply to this explainer: it covers the standard three-step RLHF process and its conceptual mechanics, not alternative alignment techniques such as Direct Preference Optimization or Constitutional AI, nor implementation-level code for any specific framework. Its discussion of limitations draws on published research, not proprietary issues from specific AI labs.
The measurable indicators to watch are improved consistency in human preference labels and reduced instances of reward hacking in model outputs. Both are observable: label consistency can be tracked through inter-annotator agreement on new preference batches, and reward hacking shows up in outputs that score highly under the reward model while degrading in fluency or accuracy relative to the SFT baseline.
Sources
- What is RLHF? - Reinforcement Learning from Human Feedback Explained - AWS — Amazon Web Services, Inc.
- What Is Reinforcement Learning From Human Feedback (RLHF)? — IBM
- AI Alignment through Reinforcement Learning from Human Feedback? Contradictions and Limitations — ARXIV
- What is RLHF? Reinforcement learning from human feedback for AI alignment — Weights & Biases
- Illustrating Reinforcement Learning from Human Feedback (RLHF) — Huggingface
- RLHF: Reinforcement Learning from Human Feedback — Chip Huyen
- RLHF 101: A Technical Tutorial on Reinforcement Learning from Human Feedback — Machine Learning Blog | ML@CMU | Carnegie Mellon University
- Reinforcement learning from human feedback - Wikipedia