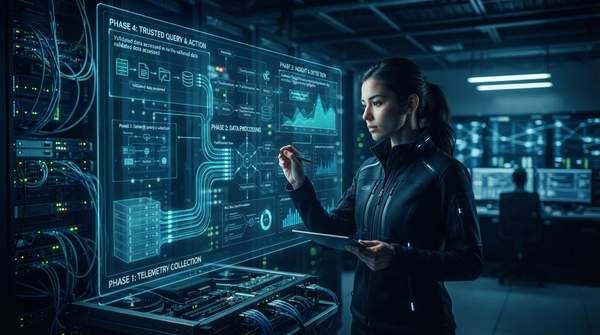
A modern data observability platform is best understood as a four-phase pipeline: collection, ingestion, storage, and query. That model, laid out by engineer Kevin Lin in his architectural analysis of modern observability platforms, gives data and MLOps teams a shared vocabulary for what happens between a metric being emitted at the source and an alert firing on a dashboard. Layered on top of that pipeline are the five data health pillars—freshness, quality, volume, schema, and lineage—that these platforms exist to monitor. Understanding both layers is what lets you evaluate tools on architecture rather than feature lists.
Understanding Data Observability: A Foundation for Reliable AI/ML
Data observability is the practice of monitoring the health of data pipelines and datasets so that problems are caught before they corrupt downstream decisions. As Databricks' editorial team defines it, it is "the ability to monitor the health of your data pipelines and datasets so you can quickly spot issues such as freshness, accuracy or completeness problems." For AI and machine learning workloads, the stakes are concrete: a stale feed or a silently changed schema doesn't just break a dashboard, it degrades a model trained on that data. Observability closes the gap between data production and data trust.
Data Observability Platform Architecture: A Four-Phase Explanatory Model
The clearest way to reason about any observability platform—open-source or commercial—is to trace a single piece of telemetry through four sequential stages. Kevin Lin's architectural breakdown describes each phase and its typical mechanics, and open-source implementations exist for the stages where the evidence supports them.
| Phase | Primary Function | Typical Mechanics | Example Open-Source Tooling |
|---|---|---|---|
| Collection | Observability data is received at the edge | Usually an agent running on a host; the initial point where telemetry is gathered from sources | OpenTelemetry, which standardizes instrumentation so you instrument once and route telemetry to any compatible backend |
| Ingestion | Collected data is processed at the destination | Batching, compression, and transformations to shape the data for storage | OpenTelemetry's standardized routing, which ClickHouse's engineering guide says "perfectly solves the ingestion problem" |
| Storage | Observability data is retained | Usually involves indexing, enabling historical analysis and efficient retrieval | ClickHouse, a data engine built for high-performance analytical queries on large telemetry volumes |
| Query | Observability data is looked up | Translating a query into GET/LIST requests against the underlying storage system | Varies by backend; the evidence reviewed here does not establish a single standard query tool |
The value of this model is diagnostic. When a platform feels slow, or its alerts are noisy, or its storage costs balloon, you can locate the problem in a specific phase rather than treating the tool as a black box. ClickHouse's engineering guide makes the same point from the user's side: when instrumentation is standardized, "the new bottleneck is the backend's ability to handle this massive flow of OpenTelemetry data"—which is an ingestion and storage question, not a collection question.
Key Pillars of Data Health: What Data Observability Measures
The pipeline above is only plumbing until you ask what it carries. Barr Moses, who created the data observability category at Monte Carlo, defines it by five pillars: freshness, quality, volume, schema, and lineage. Freshness catches data that arrives late or stops arriving. Volume flags abnormal increases or drops that signal upstream breakage. Schema detects structural changes—renamed columns, altered types—that break consumers. Quality tracks nulls, duplicates, and completeness. Lineage connects all of these to the systems affected, so a broken dashboard can be traced back to the job that broke it.
Moses notes that while these five pillars "form the foundations of reliable data products today," the category has expanded with the arrival of accessible production AI. Teams running ML pipelines now need to observe not just the data entering the pipeline but the model behavior exiting it. The pillars remain the starting point for that broader mandate.
Operational Benefits for Data and MLOps Teams
Monitoring those pillars across the four phases produces benefits that Acceldata frames in operational terms. The first is a shift in posture: "By predicting and preventing issues before they occur, you can transition from resolving and troubleshooting incidents to ensuring reliable data." Instead of firefighting broken pipelines, teams spend their time keeping pipelines from breaking.
The second set of benefits is economic. Acceldata describes analyzing workloads, identifying bottlenecks, and optimizing configurations, alongside running simulation models to forecast future capacity needs. Resource optimization follows: boosting capacity through job scheduling optimization, managing the cost of inefficient jobs, fixing hotspots, and offloading cold data to cheaper storage. For MLOps teams, that means training and inference jobs run on infrastructure that is observed rather than assumed to be healthy.
Open-Source Technologies Powering Each Observability Phase
OpenTelemetry deserves particular attention because it changes the economics of the collection and ingestion phases. ClickHouse's guide describes the pattern plainly: "You can instrument your applications once with OTel and then route telemetry to any compatible backend simply by changing a configuration file." That decoupling means the collection layer is no longer a lock-in decision—you can evaluate storage and query backends independently of how you instrument.
On the storage side, ClickHouse positions itself as the backend for exactly this flow, designed for analytical queries over massive telemetry volumes. The guide also warns against the fragmented alternative: separate, siloed tools for metrics, logs, and traces that force engineers into manual "swivel-chair analysis" during incidents—pivoting between a metrics dashboard, a log browser, and a trace viewer to connect the dots. A unified four-phase architecture is the counterargument to that fragmentation.
Making Informed Decisions for Data Reliability
To effectively evaluate and select a data observability solution, focus on how well its architecture addresses the four core phases of collection, ingestion, storage, and query, and its capability to monitor the five key data health pillars. The measurable indicator to hold any vendor or stack against is the ability of the chosen platform to provide real-time alerts and comprehensive dashboards for data freshness, volume, schema, quality, and lineage across all data pipelines. A tool that cannot demonstrate that end-to-end—from agent at the edge to alert on your desk—is describing aspiration, not architecture.
Sources
- The Architecture of Modern Observability Platforms — BIT
- What Is Data Observability? 5 Key Pillars To Know In 2026 — Monte Carlo
- What is Data Observability? — Databricks
- Best Open Source Observability Solutions (2026 Guide) — ClickHouse
- Data Observability Framework: 6 Pillars — Acceldata