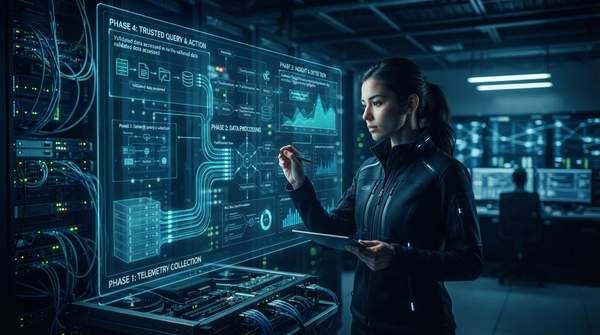
Automated root cause analysis (ARCA) systems work by running a four-stage pipeline: they ingest and normalize telemetry, detect anomalies in it, correlate those anomalies across data sources and time to infer causal links, and finally generate a prioritized, evidence-backed hypothesis about the underlying cause. Each stage depends on the one before it, and each applies a distinct category of AI or machine learning to progressively narrow a noisy incident down to a specific fault.
Understanding Automated Root Cause Analysis (ARCA)
Root cause analysis, in its traditional form, collects and analyzes data to determine the fundamental cause of an issue rather than just addressing its symptoms, with the goal of preventing recurrence. Automation applies advanced algorithms and machine learning to that process, using telemetry—logs, metrics, and traces—to detect patterns and correlations that point to the source of a problem, as ScienceLogic describes in its technical overview of the approach.
What distinguishes ARCA from a conventional observability stack is the nature of the output. Rather than surfacing raw alerts, it correlates logs, metrics, traces, deployments, and configuration changes into evidence-backed root-cause conclusions during live alert investigations, as the monitoring vendor ResolveAI explains. The investigation itself is autonomous, but the system stops short of remediation: actions on production wait for human approval.
The reason such systems exist is duration. According to ResolveAI, finding the cause—rather than fixing it—consumes most of an incident's lifetime. That is the specific gap ARCA targets, and it runs on telemetry organizations already collect rather than requiring a replacement monitoring platform.
The Multi-Stage ARCA Workflow: From Data to Diagnosis
The pipeline below sequences the components and techniques described across the evidence into a coherent workflow. It traces how raw system data becomes a diagnosis.
| Stage | Purpose | Key AI/ML Techniques |
|---|---|---|
| Data Ingestion & Normalization | Unify disparate observability signals—logs, metrics, traces, deploys, config changes—into a common schema with normalized timestamps and resolved entities. | Preprocessing and entity resolution; largely rule-based, but it determines what later stages can see. |
| Anomaly Detection & Pattern Recognition | Identify deviations from normal system behavior across data streams, focusing attention on potential problem areas. | Machine learning models such as autoencoders and isolation forests trained on normal behavior. |
| Correlation & Causal Inference | Link detected anomalies across sources and timeframes, walking dependency graphs and comparing against historical patterns to infer causal links. | Temporal scoring, event correlation, knowledge graphs, and causal inference models. |
| Hypothesis Generation & Conclusion | Produce a prioritized, evidence-backed conclusion about the most probable root cause. | Probabilistic scoring of candidate causes, with reasoning that tests hypotheses against the correlated evidence. |
Each stage refines the problem space for the next. A system-design perspective on building ARCA in production, written by engineer Raghav Sharma, emphasizes that the ingestion layer comes first precisely because correlation is impossible without a common schema: the system "processes millions of data points, walks dependency graphs, compares to historical patterns, and scores probabilities in seconds." That speed matters most under pressure—it amplifies the correlation work humans struggle with during a live incident.
Key AI/ML Techniques Driving ARCA
Three technique categories do the analytical work. Anomaly detection acts as the initial filter. Machine learning models such as autoencoders and isolation forests are trained on normal system behavior, then flag deviations that may indicate potential issues, according to an academic overview of AI-powered RCA published in the International Journal of Civil Engineering and Technology. Because these models continuously learn from historical data, their accuracy improves over time.
Correlation analysis then connects what detection surfaces. Its most important instrument is temporal: the production-design literature describes a temporal score measuring how close in time a change was to the observed impact. A deployment two minutes before errors spiked is highly suspicious; the same deployment two hours earlier is a much weaker link. Different failure types carry different temporal signatures, which the scoring must account for. Knowledge graphs and causal inference models extend this stage by representing complex relationships between system elements and inferring causal links between symptoms and underlying issues.
Natural language processing handles the third data type—unstructured text. NLP algorithms can analyze error logs, customer complaints, and maintenance reports, extracting relevant information and identifying relationships between textual elements to provide context the numeric telemetry lacks. Together, the three techniques cover the range of evidence an incident produces, though the underlying algorithms are statistical pattern matchers rather than provable deductions.
Benefits and Practical Applications of ARCA
The practical payoff of this architecture is speed and accuracy in diagnosis. The academic overview concludes that the comprehensive, multi-stage approach "often leads to more accurate and insightful root cause determinations" than manual methods, because machine learning can analyze far larger data volumes than a human investigation can hold in mind. For IT teams, that translates into faster time-to-cause during incidents and fewer recurrence-driven outages.
There are boundaries worth knowing. These systems produce hypotheses to validate, not verdicts to trust blindly. Production deployments, as ResolveAI frames it, need guardrails on actions and evaluations that measure investigation quality—and a dashboard that preserves evidence provenance so teams can verify an AI-assisted conclusion over time. As Cribl's engineering author Felicia Dorng notes, retrieval results shift: data may be late, backfilled, transformed, or moved between storage tiers, so a query returning one hundred events today may return a different set tomorrow. A conclusion is only as durable as the evidence trail behind it.
Evaluating ARCA for IT Operational Efficiency
Organizations can significantly improve IT operational efficiency by adopting ARCA systems that effectively integrate data ingestion, anomaly detection, correlation, and hypothesis generation. When evaluating a candidate system, test each stage against the model above: ask what telemetry it ingests, which anomaly models it trains, how it scores temporal correlation, and whether its conclusions preserve the evidence behind them.
The measurable indicator to track is reduced Mean Time To Resolution (MTTR) for critical incidents and a decrease in false-positive alerts. Those two metrics capture the pipeline's real contribution—faster, more confident diagnosis—and give you an objective basis for judging whether a given ARCA deployment is earning its place in your operations.